ValidMind for validation 2 — Start the validation process

Learn how to use ValidMind for your end-to-end validation process with our series of four introductory notebooks. In this second notebook, independently verify the data quality tests performed on the dataset used to train the champion.

You'll learn how to run relevant validation tests with ValidMind, log the results of those tests to the ValidMind Platform, and insert your logged test results as evidence into your validation report. You'll become familiar with the tests available in ValidMind, as well as how to run them. Running tests during validation is crucial to the effective challenge process, as we want to independently evaluate the evidence and assessments provided by the development team.

While running our tests in this notebook, we'll focus on:

For a full list of out-of-the-box tests and descriptions, use the interactive ValidMind test sandbox.

Learn by doing

Our course tailor-made for validators new to ValidMind combines this series of notebooks with more a more in-depth introduction to the ValidMind Platform — Validator Fundamentals

Prerequisites

In order to independently assess the quality of your datasets with notebook, you'll need to first have:

Need help with the above steps?

Refer to the first notebook in this series: 1 — Set up the ValidMind Library for validation

Setting up

Initialize the ValidMind Library

First, let's connect up the ValidMind Library to our model we previously registered in the ValidMind Platform:

  1. On the left sidebar that appears for your model, select Getting Started and select Validation from the Document drop-down menu.

  2. Click Copy snippet to clipboard.

  3. Next, load your model identifier credentials from an .env file or replace the placeholder with your own code snippet:

# Make sure the ValidMind Library is installed

%pip install -q validmind

# Load your model identifier credentials from an `.env` file

%load_ext dotenv
%dotenv .env

# Or replace with your code snippet

import validmind as vm

vm.init(
    # api_host="...",
    # api_key="...",
    # api_secret="...",
    # model="...",
    document="validation-report",
)
Note: you may need to restart the kernel to use updated packages.
2026-11-20 23:05:06,202 - INFO(validmind.api_client): 🎉 Connected to ValidMind!
📊 Model: [ValidMind Academy] Model validation (ID: cmalguc9y02ok199q2db381ib)
📁 Document Type: validation_report

Load the sample dataset

Let's first import the public Bank Customer Churn Prediction dataset from Kaggle, which was used to develop the dummy champion.

We'll use this dataset to review steps that should have been conducted during the initial development and documentation of the champion to ensure that the model was built correctly. By independently performing steps taken by the development team, we can confirm whether the model was built using appropriate and properly processed data.

In our below example, note that:

  • The target column, Exited has a value of 1 when a customer has churned and 0 otherwise.
  • The ValidMind Library provides a wrapper to automatically load the dataset as a Pandas DataFrame object. A Pandas Dataframe is a two-dimensional tabular data structure that makes use of rows and columns.
from validmind.datasets.classification import customer_churn as demo_dataset

print(
    f"Loaded demo dataset with: \n\n\t• Target column: '{demo_dataset.target_column}' \n\t• Class labels: {demo_dataset.class_labels}"
)

raw_df = demo_dataset.load_data()
raw_df.head()
Loaded demo dataset with: 

    • Target column: 'Exited' 
    • Class labels: {'0': 'Did not exit', '1': 'Exited'}
CreditScore Geography Gender Age Tenure Balance NumOfProducts HasCrCard IsActiveMember EstimatedSalary Exited
0 619 France Female 42 2 0.00 1 1 1 101348.88 1
1 608 Spain Female 41 1 83807.86 1 0 1 112542.58 0
2 502 France Female 42 8 159660.80 3 1 0 113931.57 1
3 699 France Female 39 1 0.00 2 0 0 93826.63 0
4 850 Spain Female 43 2 125510.82 1 1 1 79084.10 0

Verifying data quality adjustments

Let's say that thanks to the documentation submitted by the development team (Learn more: ValidMind for development), we know that the sample dataset was first modified before being used to train the champion. After performing some data quality assessments on the raw dataset, it was determined that the dataset required rebalancing, and highly correlated features were also removed.

Identify qualitative tests

During validation, we use the same data processing logic and training procedure to confirm that the model's results can be reproduced independently, so let's start by doing some data quality assessments by running a few individual tests just like the development team did.

Use the vm.tests.list_tests() function introduced by the first notebook in this series in combination with vm.tests.list_tags() and vm.tests.list_tasks() to find which prebuilt tests are relevant for data quality assessment:

  • tasks represent the kind of modeling task associated with a test. Here we'll focus on classification tasks.
  • tags are free-form descriptions providing more details about the test, for example, what category the test falls into. Here we'll focus on the data_quality tag.
# Get the list of available task types
sorted(vm.tests.list_tasks())
['classification',
 'clustering',
 'data_validation',
 'feature_extraction',
 'monitoring',
 'nlp',
 'regression',
 'residual_analysis',
 'text_classification',
 'text_generation',
 'text_qa',
 'text_summarization',
 'time_series_forecasting',
 'visualization']
# Get the list of available tags
sorted(vm.tests.list_tags())
['AUC',
 'analysis',
 'anomaly',
 'anomaly_detection',
 'bias_and_fairness',
 'binary_classification',
 'calibration',
 'categorical_data',
 'classification',
 'classification_metrics',
 'clustering',
 'conceptual_soundness',
 'correlation',
 'credit_risk',
 'data_analysis',
 'data_distribution',
 'data_quality',
 'data_validation',
 'descriptive_statistics',
 'dimensionality_reduction',
 'distribution',
 'embeddings',
 'feature_importance',
 'feature_selection',
 'few_shot',
 'forecasting',
 'frequency_analysis',
 'kmeans',
 'linear_regression',
 'llm',
 'logistic_regression',
 'metadata',
 'model_comparison',
 'model_diagnosis',
 'model_explainability',
 'model_interpretation',
 'model_performance',
 'model_predictions',
 'model_selection',
 'model_training',
 'model_validation',
 'multiclass_classification',
 'multicollinearity',
 'nlp',
 'normality',
 'numerical_data',
 'outlier',
 'outliers',
 'qualitative',
 'rag_performance',
 'ragas',
 'regression',
 'retrieval_performance',
 'robustness',
 'scorecard',
 'seasonality',
 'segment_analysis',
 'sensitivity_analysis',
 'sklearn',
 'specification',
 'stability',
 'stationarity',
 'statistical_test',
 'statistics',
 'statsmodels',
 'stress_testing',
 'tabular_data',
 'text_data',
 'threshold_optimization',
 'time_series_data',
 'uncertainty',
 'unit_root_test',
 'visualization',
 'zero_shot']

You can pass tags and tasks as parameters to the vm.tests.list_tests() function to filter the tests based on the tags and task types.

For example, to find tests related to tabular data quality for classification models, you can call list_tests() like this:

vm.tests.list_tests(task="classification", tags=["tabular_data", "data_quality"])
ID Name Description Has Figure Has Table Required Inputs Params Tags Tasks
validmind.data_validation.ClassImbalance Class Imbalance Evaluates and quantifies class distribution imbalance in a dataset used by a machine learning model.... True True ['dataset'] {'min_percent_threshold': {'type': 'int', 'default': 10}} ['tabular_data', 'binary_classification', 'multiclass_classification', 'data_quality'] ['classification']
validmind.data_validation.DescriptiveStatistics Descriptive Statistics Performs a detailed descriptive statistical analysis of both numerical and categorical data within a model's... False True ['dataset'] {} ['tabular_data', 'time_series_data', 'data_quality'] ['classification', 'regression']
validmind.data_validation.Duplicates Duplicates Tests dataset for duplicate entries, ensuring model reliability via data quality verification.... False True ['dataset'] {'min_threshold': {'type': '_empty', 'default': 1}} ['tabular_data', 'data_quality', 'text_data'] ['classification', 'regression']
validmind.data_validation.HighCardinality High Cardinality Assesses the number of unique values in categorical columns to detect high cardinality and potential overfitting.... False True ['dataset'] {'num_threshold': {'type': 'int', 'default': 100}, 'percent_threshold': {'type': 'float', 'default': 0.1}, 'threshold_type': {'type': 'str', 'default': 'percent'}} ['tabular_data', 'data_quality', 'categorical_data'] ['classification', 'regression']
validmind.data_validation.HighPearsonCorrelation High Pearson Correlation Identifies highly correlated feature pairs in a dataset suggesting feature redundancy or multicollinearity.... False True ['dataset'] {'max_threshold': {'type': 'float', 'default': 0.3}, 'top_n_correlations': {'type': 'int', 'default': 10}, 'feature_columns': {'type': 'list', 'default': None}} ['tabular_data', 'data_quality', 'correlation'] ['classification', 'regression']
validmind.data_validation.MissingValues Missing Values Evaluates dataset quality by ensuring missing value percentage across all features does not exceed a set threshold.... False True ['dataset'] {'min_percentage_threshold': {'type': 'float', 'default': 1.0}} ['tabular_data', 'data_quality'] ['classification', 'regression']
validmind.data_validation.MissingValuesBarPlot Missing Values Bar Plot Assesses the percentage and distribution of missing values in the dataset via a bar plot, with emphasis on... True False ['dataset'] {'threshold': {'type': 'int', 'default': 80}, 'fig_height': {'type': 'int', 'default': 600}} ['tabular_data', 'data_quality', 'visualization'] ['classification', 'regression']
validmind.data_validation.Skewness Skewness Evaluates the skewness of numerical data in a dataset to check against a defined threshold, aiming to ensure data... False True ['dataset'] {'max_threshold': {'type': '_empty', 'default': 1}} ['data_quality', 'tabular_data'] ['classification', 'regression']
validmind.plots.BoxPlot Box Plot Generates customizable box plots for numerical features in a dataset with optional grouping using Plotly.... True False ['dataset'] {'columns': {'type': 'Optional', 'default': None}, 'group_by': {'type': 'Optional', 'default': None}, 'width': {'type': 'int', 'default': 1800}, 'height': {'type': 'int', 'default': 1200}, 'colors': {'type': 'Optional', 'default': None}, 'show_outliers': {'type': 'bool', 'default': True}, 'title_prefix': {'type': 'str', 'default': 'Box Plot of'}} ['tabular_data', 'visualization', 'data_quality'] ['classification', 'regression', 'clustering']
validmind.plots.HistogramPlot Histogram Plot Generates customizable histogram plots for numerical features in a dataset using Plotly.... True False ['dataset'] {'columns': {'type': 'Optional', 'default': None}, 'bins': {'type': 'Union', 'default': 30}, 'color': {'type': 'str', 'default': 'steelblue'}, 'opacity': {'type': 'float', 'default': 0.7}, 'show_kde': {'type': 'bool', 'default': True}, 'normalize': {'type': 'bool', 'default': False}, 'log_scale': {'type': 'bool', 'default': False}, 'title_prefix': {'type': 'str', 'default': 'Histogram of'}, 'width': {'type': 'int', 'default': 1200}, 'height': {'type': 'int', 'default': 800}, 'n_cols': {'type': 'int', 'default': 2}, 'vertical_spacing': {'type': 'float', 'default': 0.15}, 'horizontal_spacing': {'type': 'float', 'default': 0.1}} ['tabular_data', 'visualization', 'data_quality'] ['classification', 'regression', 'clustering']
validmind.stats.DescriptiveStats Descriptive Stats Provides comprehensive descriptive statistics for numerical features in a dataset.... False True ['dataset'] {'columns': {'type': 'Optional', 'default': None}, 'include_advanced': {'type': 'bool', 'default': True}, 'confidence_level': {'type': 'float', 'default': 0.95}} ['tabular_data', 'statistics', 'data_quality'] ['classification', 'regression', 'clustering']
Want to learn more about navigating ValidMind tests?

Refer to our notebook outlining the utilities available for viewing and understanding available ValidMind tests: Explore tests

Initialize the ValidMind dataset

With the individual tests we want to run identified, the next step is to connect your data with a ValidMind Dataset object. This step is always necessary every time you want to connect a dataset to documentation and produce test results through ValidMind, but you only need to do it once per dataset.

Initialize a ValidMind dataset object using the init_dataset function from the ValidMind (vm) module. For this example, we'll pass in the following arguments:

  • dataset — The raw dataset that you want to provide as input to tests.
  • input_id — A unique identifier that allows tracking what inputs are used when running each individual test.
  • target_column — A required argument if tests require access to true values. This is the name of the target column in the dataset.
# vm_raw_dataset is now a VMDataset object that you can pass to any ValidMind test
vm_raw_dataset = vm.init_dataset(
    dataset=raw_df,
    input_id="raw_dataset",
    target_column="Exited",
)

Run data quality tests

Now that we know how to initialize a ValidMind dataset object, we're ready to run some tests!

You run individual tests by calling the run_test function provided by the validmind.tests module. For the examples below, we'll pass in the following arguments:

  • test_id — The ID of the test to run, as seen in the ID column when you run list_tests.
  • params — A dictionary of parameters for the test. These will override any default_params set in the test definition.

Run tabular data tests

The inputs expected by a test can also be found in the test definition — let's take validmind.data_validation.DescriptiveStatistics as an example.

Note that the output of the describe_test() function below shows that this test expects a dataset as input:

vm.tests.describe_test("validmind.data_validation.DescriptiveStatistics")
▶ Test: Descriptive Statistics ('validmind.data_validation.DescriptiveStatistics')

Now, let's run a few tests to assess the quality of the dataset:

result2 = vm.tests.run_test(
    test_id="validmind.data_validation.ClassImbalance",
    inputs={"dataset": vm_raw_dataset},
    params={"min_percent_threshold": 30},
)

❌ Class Imbalance

The Class Imbalance test evaluates the distribution of target classes by measuring each class’s share of total observations against a defined minimum percentage threshold. In this run, the target variable Exited is shown across two classes with a configured threshold of 30%. The results table and accompanying bar chart indicate that class Exited=0 represents 79.80% of rows and class Exited=1 represents 20.20% of rows, with pass/fail status reported for each class based on the threshold.

Key insights:

  • Majority class dominates distribution: Exited=0 accounts for 79.80% of observations, making it the predominant class in the target distribution.
  • Minority class falls below threshold: Exited=1 represents 20.20% of observations, which is below the configured 30% minimum threshold and is marked as Fail.
  • Asymmetric class proportions observed: The class shares differ materially, with the majority class comprising nearly four times the proportion of the minority class.

The results show a two-class target distribution with a pronounced skew toward Exited=0. Under the 30% threshold used in this test, the majority class passes and the minority class fails, indicating that only one class satisfies the minimum representation criterion. The observed class proportions document a clear imbalance in the target variable as evaluated by this test.

Parameters:

{
  "min_percent_threshold": 30
}
            

Tables

Exited Class Imbalance

Exited Percentage of Rows (%) Pass/Fail
0 79.80% Pass
1 20.20% Fail

Figures

ValidMind Figure validmind.data_validation.ClassImbalance:2b56

The output above shows that the validmind.data_validation.ClassImbalance test did not pass according to the value we set for min_percent_threshold — great, this matches what was reported by the development team.

To address this issue, we'll re-run the test on some processed data. In this case let's apply a very simple rebalancing technique to the dataset:

import pandas as pd

raw_copy_df = raw_df.sample(frac=1)  # Create a copy of the raw dataset

# Create a balanced dataset with the same number of exited and not exited customers
exited_df = raw_copy_df.loc[raw_copy_df["Exited"] == 1]
not_exited_df = raw_copy_df.loc[raw_copy_df["Exited"] == 0].sample(n=exited_df.shape[0])

balanced_raw_df = pd.concat([exited_df, not_exited_df])
balanced_raw_df = balanced_raw_df.sample(frac=1, random_state=42)

With this new balanced dataset, you can re-run the individual test to see if it now passes the class imbalance test requirement.

As this is technically a different dataset, remember to first initialize a new ValidMind Dataset object to pass in as input as required by run_test():

# Register new data and now 'balanced_raw_dataset' is the new dataset object of interest
vm_balanced_raw_dataset = vm.init_dataset(
    dataset=balanced_raw_df,
    input_id="balanced_raw_dataset",
    target_column="Exited",
)
# Pass the initialized `balanced_raw_dataset` as input into the test run
result = vm.tests.run_test(
    test_id="validmind.data_validation.ClassImbalance",
    inputs={"dataset": vm_balanced_raw_dataset},
    params={"min_percent_threshold": 30},
)

✅ Class Imbalance

The Class Imbalance test evaluates the distribution of target classes in the dataset by measuring the proportion of records in each class against a specified minimum threshold. In this run, the target variable Exited is summarized across two classes, with each class representing 50.00% of the records. The applied minimum percentage threshold is 30%, and the table and accompanying bar chart show the relative share and pass/fail status for each class.

Key insights:

  • Target classes are evenly split: Both Exited = 0 and Exited = 1 account for 50.00% of the dataset, indicating an equal class distribution in the tested sample.
  • All classes pass threshold test: Each class exceeds the configured minimum percentage threshold of 30%, and both are marked as Pass in the test output.
  • No underrepresented class observed: The results show no class with a share below the defined threshold, and the plot confirms equal bar heights across the two target classes.

The results show a balanced binary target distribution for Exited, with both classes present at identical proportions and both meeting the configured threshold criterion. Based on the reported percentages and pass/fail statuses, the test does not identify class imbalance in the evaluated dataset.

Parameters:

{
  "min_percent_threshold": 30
}
            

Tables

Exited Class Imbalance

Exited Percentage of Rows (%) Pass/Fail
0 50.00% Pass
1 50.00% Pass

Figures

ValidMind Figure validmind.data_validation.ClassImbalance:31f9

Remove highly correlated features

Next, let's also remove highly correlated features from our dataset as outlined by the development team. Removing highly correlated features helps make the model simpler, more stable, and easier to understand.

You can utilize the output from a ValidMind test for further use — in this below example, to retrieve the list of features with the highest correlation coefficients and use them to reduce the final list of features for modeling.

First, we'll run validmind.data_validation.HighPearsonCorrelation with the balanced_raw_dataset we initialized previously as input as is for comparison with later runs:

corr_result = vm.tests.run_test(
    test_id="validmind.data_validation.HighPearsonCorrelation",
    params={"max_threshold": 0.3},
    inputs={"dataset": vm_balanced_raw_dataset},
)

❌ High Pearson Correlation

The High Pearson Correlation test evaluates pairwise linear relationships among features to identify potentially redundant or highly collinear variable pairs. The result table reports the top correlations observed in the dataset, including the feature pair, Pearson correlation coefficient, and pass/fail status against the configured threshold of 0.3. Among the 10 reported pairs, coefficients range from -0.1868 to 0.3568. Only one pair exceeds the threshold and is marked as failing, while the remaining reported correlations are below the threshold and marked as passing.

Key insights:

  • Single threshold breach identified: The pair (Age, Exited) has the largest absolute correlation at 0.3568 and is the only reported pair with a Fail status under the 0.3 threshold.
  • Remaining reported correlations are modest: All other listed feature pairs have absolute correlation coefficients of 0.1868 or lower, indicating substantially weaker linear relationships than the leading pair.
  • Top correlations are concentrated near zero: Most reported coefficients fall within a narrow range close to zero, including values such as 0.0521, -0.0465, 0.0426, -0.0410, -0.0408, and -0.0395.
  • Both positive and negative relationships are present: The reported pairs include both positive correlations, such as (Balance, Exited) = 0.1512, and negative correlations, such as (IsActiveMember, Exited) = -0.1868 and (Balance, NumOfProducts) = -0.1729.

The reported correlation structure shows one feature pair above the configured Pearson correlation threshold and nine reported pairs below it. The strongest observed relationship is between Age and Exited, while the rest of the listed relationships are materially smaller in magnitude. Overall, the top reported pairwise linear relationships are limited in number and predominantly low in absolute strength.

Parameters:

{
  "max_threshold": 0.3
}
            

Tables

Columns Coefficient Pass/Fail
(Age, Exited) 0.3568 Fail
(IsActiveMember, Exited) -0.1868 Pass
(Balance, NumOfProducts) -0.1729 Pass
(Balance, Exited) 0.1512 Pass
(NumOfProducts, IsActiveMember) 0.0521 Pass
(NumOfProducts, Exited) -0.0465 Pass
(Tenure, EstimatedSalary) 0.0426 Pass
(Age, NumOfProducts) -0.0410 Pass
(Age, EstimatedSalary) -0.0408 Pass
(HasCrCard, IsActiveMember) -0.0395 Pass

The output above shows that the test did not pass according to the value we set for max_threshold — as reported and expected.

corr_result is an object of type TestResult. We can inspect the result object to see what the test has produced:

print(type(corr_result))
print("Result ID: ", corr_result.result_id)
print("Params: ", corr_result.params)
print("Passed: ", corr_result.passed)
print("Tables: ", corr_result.tables)
<class 'validmind.vm_models.result.result.TestResult'>
Result ID:  validmind.data_validation.HighPearsonCorrelation
Params:  {'max_threshold': 0.3}
Passed:  False
Tables:  [ResultTable]

Let's remove the highly correlated features and create a new VM dataset object.

We'll begin by checking out the table in the result and extracting a list of features that failed the test:

# Extract table from `corr_result.tables`
features_df = corr_result.tables[0].data
features_df
Columns Coefficient Pass/Fail
0 (Age, Exited) 0.3568 Fail
1 (IsActiveMember, Exited) -0.1868 Pass
2 (Balance, NumOfProducts) -0.1729 Pass
3 (Balance, Exited) 0.1512 Pass
4 (NumOfProducts, IsActiveMember) 0.0521 Pass
5 (NumOfProducts, Exited) -0.0465 Pass
6 (Tenure, EstimatedSalary) 0.0426 Pass
7 (Age, NumOfProducts) -0.0410 Pass
8 (Age, EstimatedSalary) -0.0408 Pass
9 (HasCrCard, IsActiveMember) -0.0395 Pass
# Extract list of features that failed the test
high_correlation_features = features_df[features_df["Pass/Fail"] == "Fail"]["Columns"].tolist()
high_correlation_features
['(Age, Exited)']

Next, extract the feature names from the list of strings (example: (Age, Exited) > Age):

high_correlation_features = [feature.split(",")[0].strip("()") for feature in high_correlation_features]
high_correlation_features
['Age']

Now, it's time to re-initialize the dataset with the highly correlated features removed.

Note the use of a different input_id. This allows tracking the inputs used when running each individual test.

# Remove the highly correlated features from the dataset
balanced_raw_no_age_df = balanced_raw_df.drop(columns=high_correlation_features)

# Re-initialize the dataset object
vm_raw_dataset_preprocessed = vm.init_dataset(
    dataset=balanced_raw_no_age_df,
    input_id="raw_dataset_preprocessed",
    target_column="Exited",
)

Re-running the test with the reduced feature set should pass the test:

corr_result = vm.tests.run_test(
    test_id="validmind.data_validation.HighPearsonCorrelation",
    params={"max_threshold": 0.3},
    inputs={"dataset": vm_raw_dataset_preprocessed},
)

✅ High Pearson Correlation

The High Pearson Correlation test evaluates pairwise linear relationships among features to identify potentially redundant variables or multicollinearity. The results table reports the top feature pairs by absolute Pearson correlation coefficient, along with Pass/Fail status using a threshold of 0.3. In this run, the reported coefficients range from -0.1868 to 0.1512, and all listed pairs are marked Pass. The strongest observed relationships are shown for (IsActiveMember, Exited), (Balance, NumOfProducts), and (Balance, Exited).

Key insights:

  • No pair exceeds threshold: All reported feature pairs pass the test against the configured maximum threshold of 0.3. The largest absolute coefficient is 0.1868 for (IsActiveMember, Exited), which remains below the threshold.
  • Observed relationships are weak: The top reported correlations are modest in magnitude, with coefficients of -0.1868 for (IsActiveMember, Exited), -0.1729 for (Balance, NumOfProducts), and 0.1512 for (Balance, Exited). The remaining listed coefficients are all within approximately ±0.05.
  • Both positive and negative correlations appear: The table includes both inverse and direct linear relationships. Negative correlations are present for pairs such as (IsActiveMember, Exited) and (Balance, NumOfProducts), while positive correlations are present for pairs such as (Balance, Exited) and (Tenure, EstimatedSalary).

The reported correlation structure is limited to low-magnitude pairwise linear relationships among the listed feature combinations. No reported pair breaches the 0.3 threshold, and the strongest coefficients remain materially below that level. Collectively, the results indicate that the top observed pairwise Pearson correlations in this run are weak and uniformly classified as passing.

Parameters:

{
  "max_threshold": 0.3
}
            

Tables

Columns Coefficient Pass/Fail
(IsActiveMember, Exited) -0.1868 Pass
(Balance, NumOfProducts) -0.1729 Pass
(Balance, Exited) 0.1512 Pass
(NumOfProducts, IsActiveMember) 0.0521 Pass
(NumOfProducts, Exited) -0.0465 Pass
(Tenure, EstimatedSalary) 0.0426 Pass
(HasCrCard, IsActiveMember) -0.0395 Pass
(Tenure, IsActiveMember) -0.0279 Pass
(Tenure, Exited) -0.0268 Pass
(Tenure, HasCrCard) 0.0242 Pass

You can also plot the correlation matrix to visualize the new correlation between features:

corr_result = vm.tests.run_test(
    test_id="validmind.data_validation.PearsonCorrelationMatrix",
    inputs={"dataset": vm_raw_dataset_preprocessed},
)

Pearson Correlation Matrix

The PearsonCorrelationMatrix test evaluates linear dependency among numerical variables by displaying pairwise Pearson correlation coefficients in a heat map. The matrix covers CreditScore, Tenure, Balance, NumOfProducts, HasCrCard, IsActiveMember, EstimatedSalary, and Exited, with coefficients ranging from -1 to 1 and diagonal values of 1.0. Off-diagonal values shown in the figure are concentrated close to zero, with the largest magnitudes observed at -0.19, -0.17, and 0.15.

Key insights:

  • Correlations are uniformly weak: All off-diagonal correlations in the matrix remain far below the 0.7 absolute threshold highlighted by the test methodology. The observed pairwise relationships are small in magnitude across the full set of numerical variables.
  • Exited shows limited linear association: Exited has weak correlations with the other variables, including 0.15 with Balance, -0.19 with IsActiveMember, -0.05 with NumOfProducts, and values between -0.03 and 0.01 for the remaining variables.
  • Largest non-target dependency is modest: The strongest non-diagonal relationship among predictors is between Balance and NumOfProducts at -0.17. Other predictor-predictor correlations, such as 0.05 between NumOfProducts and IsActiveMember and 0.04 between Tenure and EstimatedSalary, are minimal.
  • No concentrated correlation clusters appear: The heat map does not show groups of variables with consistently elevated positive or negative correlations. Most cells are near zero, indicating limited linear co-movement across the numerical feature set.

The correlation structure in this result is sparse and low in magnitude across both predictor-predictor and predictor-target pairs. No pairwise relationship approaches the high-correlation threshold described in the test methodology, and the largest observed associations remain modest. Collectively, the result indicates limited linear redundancy among the numerical variables included in the matrix.

Figures

ValidMind Figure validmind.data_validation.PearsonCorrelationMatrix:e694

Documenting test results

Now that we've done some analysis on two different datasets, we can use ValidMind to easily document why certain things were done to our raw data with testing to support it. Every test result returned by the run_test() function has a .log() method that can be used to send the test results to the ValidMind Platform.

When logging validation test results to the platform, you'll need to manually add those results to the desired section of the validation report. To demonstrate how to add test results to your validation report, we'll log our data quality tests and insert the results via the ValidMind Platform.

Configure and run comparison tests

Below, we'll perform comparison tests between the original raw dataset (raw_dataset) and the final preprocessed (raw_dataset_preprocessed) dataset, again logging the results to the ValidMind Platform.

We can specify all the tests we'd ike to run in a dictionary called test_config, and we'll pass in the following arguments for each test:

  • params: Individual test parameters.
  • input_grid: Individual test inputs to compare. In this case, we'll input our two datasets for comparison.

Note here that the input_grid expects the input_id of the dataset as the value rather than the variable name we specified:

# Individual test config with inputs specified
test_config = {
    "validmind.data_validation.ClassImbalance": {
        "input_grid": {"dataset": ["raw_dataset", "raw_dataset_preprocessed"]},
        "params": {"min_percent_threshold": 30}
    },
    "validmind.data_validation.HighPearsonCorrelation": {
        "input_grid": {"dataset": ["raw_dataset", "raw_dataset_preprocessed"]},
        "params": {"max_threshold": 0.3}
    },
}

Then batch run and log our tests in test_config:

for t in test_config:
    print(t)
    try:
        # Check if test has input_grid
        if 'input_grid' in test_config[t]:
            # For tests with input_grid, pass the input_grid configuration
            if 'params' in test_config[t]:
                vm.tests.run_test(t, input_grid=test_config[t]['input_grid'], params=test_config[t]['params']).log()
            else:
                vm.tests.run_test(t, input_grid=test_config[t]['input_grid']).log()
        else:
            # Original logic for regular inputs
            if 'params' in test_config[t]:
                vm.tests.run_test(t, inputs=test_config[t]['inputs'], params=test_config[t]['params']).log()
            else:
                vm.tests.run_test(t, inputs=test_config[t]['inputs']).log()
    except Exception as e:
        print(f"Error running test {t}: {str(e)}")
validmind.data_validation.ClassImbalance

❌ Class Imbalance

The Class Imbalance test evaluates the distribution of target classes by measuring the percentage of records in each class against a minimum threshold. In this run, results are reported for both raw_dataset and raw_dataset_preprocessed using a min_percent_threshold of 30%. The output table and accompanying bar charts show the class proportions for Exited = 0 and Exited = 1, along with pass/fail outcomes for each class in each dataset.

Key insights:

  • Raw dataset is imbalanced: In raw_dataset, Exited = 0 represents 79.80% of rows and passes the 30% threshold, while Exited = 1 represents 20.20% and fails the threshold.
  • Preprocessed dataset is balanced: In raw_dataset_preprocessed, both Exited = 0 and Exited = 1 each account for 50.00% of rows, and both classes pass the threshold.
  • Class proportions changed materially after preprocessing: The minority class share increases from 20.20% in raw_dataset to 50.00% in raw_dataset_preprocessed, while the majority class share decreases from 79.80% to 50.00%.

The results show a clear difference in class distribution between the original and preprocessed datasets. The original dataset contains an uneven target distribution, with the Exited = 1 class below the configured 30% minimum, whereas the preprocessed dataset exhibits an even 50/50 split across classes and passes the test for both classes. This indicates that preprocessing materially altered the target class balance reflected in the test output.

Parameters:

{
  "min_percent_threshold": 30
}
            

Tables

dataset Exited Percentage of Rows (%) Pass/Fail
raw_dataset 0 79.80% Pass
raw_dataset 1 20.20% Fail
raw_dataset_preprocessed 0 50.00% Pass
raw_dataset_preprocessed 1 50.00% Pass

Figures

ValidMind Figure validmind.data_validation.ClassImbalance:0d1e
ValidMind Figure validmind.data_validation.ClassImbalance:6f1d
2026-11-20 23:05:49,830 - INFO(validmind.vm_models.result.result): Test driven block with result_id validmind.data_validation.ClassImbalance does not exist in model's document
validmind.data_validation.HighPearsonCorrelation

❌ High Pearson Correlation

The High Pearson Correlation test evaluates pairwise linear relationships between features to identify highly correlated variable pairs that may indicate redundancy or multicollinearity. The results report the top correlations for both raw_dataset and raw_dataset_preprocessed, using a maximum threshold of 0.3 to assign Pass or Fail outcomes. Reported coefficients span both positive and negative values, with one failing pair in the raw dataset and all listed pairs in the preprocessed dataset passing the threshold. The output therefore shows the strongest observed feature relationships by dataset along with their corresponding correlation magnitudes and statuses.

Key insights:

  • One threshold breach in raw data: In raw_dataset, the pair (Balance, NumOfProducts) records a correlation coefficient of -0.3045, which exceeds the absolute threshold of 0.3 and is marked Fail.

  • Preprocessing removed listed threshold breaches: In raw_dataset_preprocessed, the strongest listed correlation is (IsActiveMember, Exited) at -0.1868, and all reported pairs are marked Pass.

  • Raw data contains the strongest observed relationships: The largest absolute correlations among the reported results appear in raw_dataset, including (Balance, NumOfProducts) at -0.3045 and (Age, Exited) at 0.281, both materially higher than the largest listed correlations in the preprocessed dataset.

  • Observed correlations are generally modest: Aside from the single failing pair, all reported coefficients fall within -0.1868 to 0.281 in absolute terms across the two datasets, indicating that the listed pairwise linear relationships are limited in magnitude.

Overall, the test results show a limited set of relatively small pairwise linear relationships across the reported feature pairs, with one raw-data correlation marginally exceeding the configured threshold. The preprocessed dataset shows lower reported correlation magnitudes and no listed failures. Taken together, the reported results indicate that the strongest observed pairwise linear association is concentrated in the raw dataset rather than the preprocessed dataset.

Parameters:

{
  "max_threshold": 0.3
}
            

Tables

dataset Columns Coefficient Pass/Fail
raw_dataset (Balance, NumOfProducts) -0.3045 Fail
raw_dataset (Age, Exited) 0.2810 Pass
raw_dataset (IsActiveMember, Exited) -0.1515 Pass
raw_dataset (Balance, Exited) 0.1174 Pass
raw_dataset (Age, IsActiveMember) 0.0873 Pass
raw_dataset (NumOfProducts, Exited) -0.0523 Pass
raw_dataset (Age, NumOfProducts) -0.0306 Pass
raw_dataset (CreditScore, IsActiveMember) 0.0306 Pass
raw_dataset (Tenure, IsActiveMember) -0.0293 Pass
raw_dataset (Age, Balance) 0.0290 Pass
raw_dataset_preprocessed (IsActiveMember, Exited) -0.1868 Pass
raw_dataset_preprocessed (Balance, NumOfProducts) -0.1729 Pass
raw_dataset_preprocessed (Balance, Exited) 0.1512 Pass
raw_dataset_preprocessed (NumOfProducts, IsActiveMember) 0.0521 Pass
raw_dataset_preprocessed (NumOfProducts, Exited) -0.0465 Pass
raw_dataset_preprocessed (Tenure, EstimatedSalary) 0.0426 Pass
raw_dataset_preprocessed (HasCrCard, IsActiveMember) -0.0395 Pass
raw_dataset_preprocessed (Tenure, IsActiveMember) -0.0279 Pass
raw_dataset_preprocessed (Tenure, Exited) -0.0268 Pass
raw_dataset_preprocessed (Tenure, HasCrCard) 0.0242 Pass
2026-11-20 23:05:57,196 - INFO(validmind.vm_models.result.result): Test driven block with result_id validmind.data_validation.HighPearsonCorrelation does not exist in model's document
Note the output returned indicating that a test-driven block doesn't currently exist in your documentation for some test IDs.

That's expected, as when we run validations tests the results logged need to be manually added to your report as part of your compliance assessment process within the ValidMind Platform.

Log tests with unique identifiers

Next, we'll use the previously initialized vm_balanced_raw_dataset (that still has a highly correlated Age column) as input to run an individual test, then log the result to the ValidMind Platform.

When running individual tests, you can use a custom result_id to tag the individual result with a unique identifier:

  • This result_id can be appended to test_id with a : separator.
  • The balanced_raw_dataset result identifier will correspond to the balanced_raw_dataset input, the dataset that still has the Age column.
result = vm.tests.run_test(
    test_id="validmind.data_validation.HighPearsonCorrelation:balanced_raw_dataset",
    params={"max_threshold": 0.3},
    inputs={"dataset": vm_balanced_raw_dataset},
)
result.log()

❌ High Pearson Correlation Balanced Raw Dataset

The High Pearson Correlation test evaluates pairwise linear relationships between features to identify highly correlated variable pairs that may indicate redundancy or multicollinearity. The result table lists the top correlations observed in the balanced raw dataset together with their Pearson coefficients and pass/fail status against the configured absolute threshold of 0.3. Among the reported pairs, coefficients range from -0.1868 to 0.3568, and only one pair exceeds the threshold.

Key insights:

  • Single threshold breach identified: The pair (Age, Exited) has a Pearson correlation coefficient of 0.3568, making it the only reported relationship that fails the 0.3 threshold.
  • Remaining reported correlations are low: All other listed pairs pass the test, with absolute coefficients at or below 0.1868, including (IsActiveMember, Exited) at -0.1868 and (Balance, NumOfProducts) at -0.1729.
  • Top reported relationships are concentrated near zero: Outside the highest-ranked pair, the remaining coefficients are relatively small in magnitude, with several near-zero relationships such as (Tenure, EstimatedSalary) at 0.0426, (Age, EstimatedSalary) at -0.0408, and (HasCrCard, IsActiveMember) at -0.0395.
  • Both positive and negative associations are present: The reported results include positive correlations, such as (Balance, Exited) at 0.1512, and negative correlations, such as (NumOfProducts, Exited) at -0.0465, indicating mixed linear association directions across the listed feature pairs.

The reported correlation structure is sparse at the configured threshold, with only (Age, Exited) exceeding the 0.3 cutoff. All other listed feature pairs remain below the threshold and are low in magnitude relative to the top-ranked pair. Overall, the result indicates that the strongest observed linear relationship in the reported output is isolated rather than widespread across the listed variables.

Parameters:

{
  "max_threshold": 0.3
}
            

Tables

Columns Coefficient Pass/Fail
(Age, Exited) 0.3568 Fail
(IsActiveMember, Exited) -0.1868 Pass
(Balance, NumOfProducts) -0.1729 Pass
(Balance, Exited) 0.1512 Pass
(NumOfProducts, IsActiveMember) 0.0521 Pass
(NumOfProducts, Exited) -0.0465 Pass
(Tenure, EstimatedSalary) 0.0426 Pass
(Age, NumOfProducts) -0.0410 Pass
(Age, EstimatedSalary) -0.0408 Pass
(HasCrCard, IsActiveMember) -0.0395 Pass
2026-11-20 23:06:03,759 - INFO(validmind.vm_models.result.result): Test driven block with result_id validmind.data_validation.HighPearsonCorrelation:balanced_raw_dataset does not exist in model's document

Add test results to reporting

With some test results logged, let's head to the model we connected to at the beginning of this notebook and learn how to insert a test result into our validation report. (Learn more: Assess compliance)

While the example below focuses on a specific test result, you can follow the same general procedure for your other results:

  1. From the Inventory in the ValidMind Platform, go to the model you connected to earlier.

  2. In the left sidebar that appears for your model, click Validation under Documents.

  3. Click on 2.2.1. Data Quality to expand that section.

  4. Under the Class Imbalance Assessment guideline, click Evidence to expand the evidence panel.

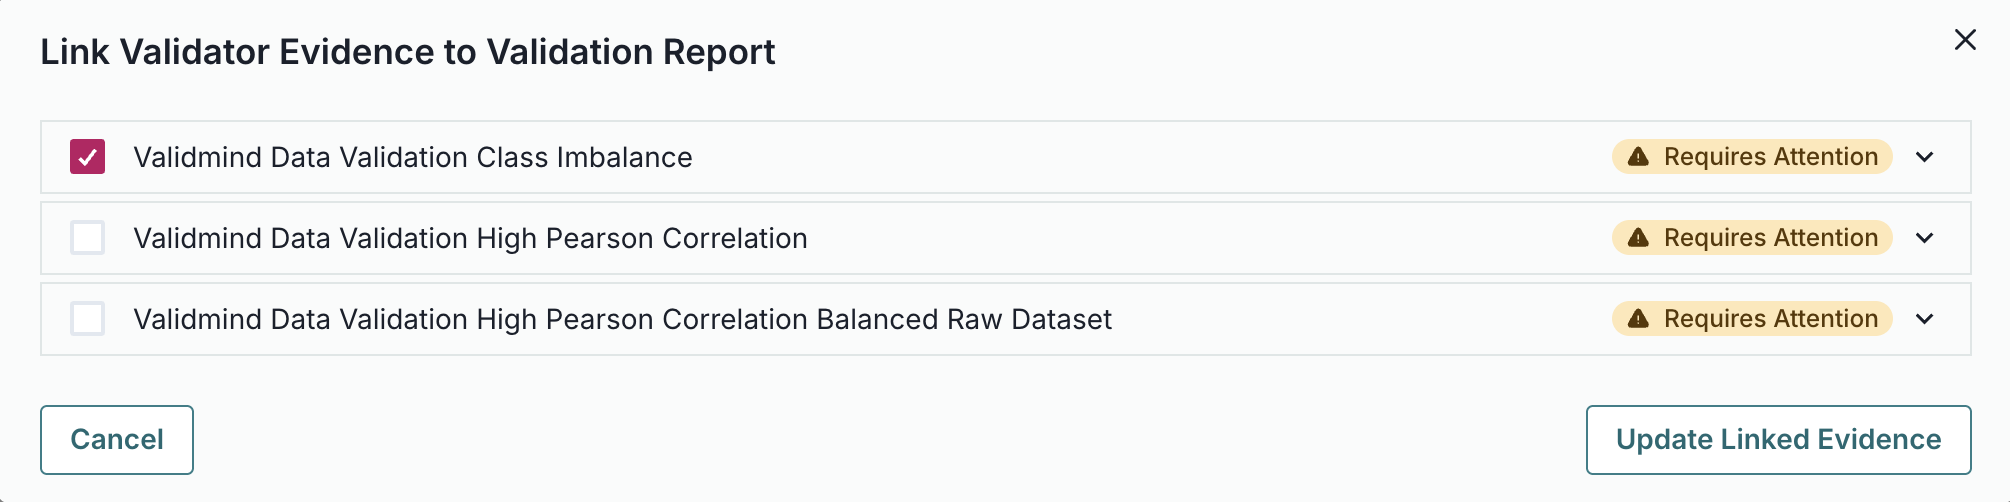
  5. Click Link Evidence, then select Validator Evidence.

  6. Select the Class Imbalance test results we logged: ValidMind Data Validation Class Imbalance

    Screenshot showing the ClassImbalance test selected

  7. Click Update Linked Evidence to add the test results to the validation report.

  8. Confirm that the results for the Class Imbalance test you inserted has been correctly inserted into section 2.2.1. Data Quality of the report.

    • Note that these test results are flagged as Requires Attention — as they include comparative results from our initial raw dataset.
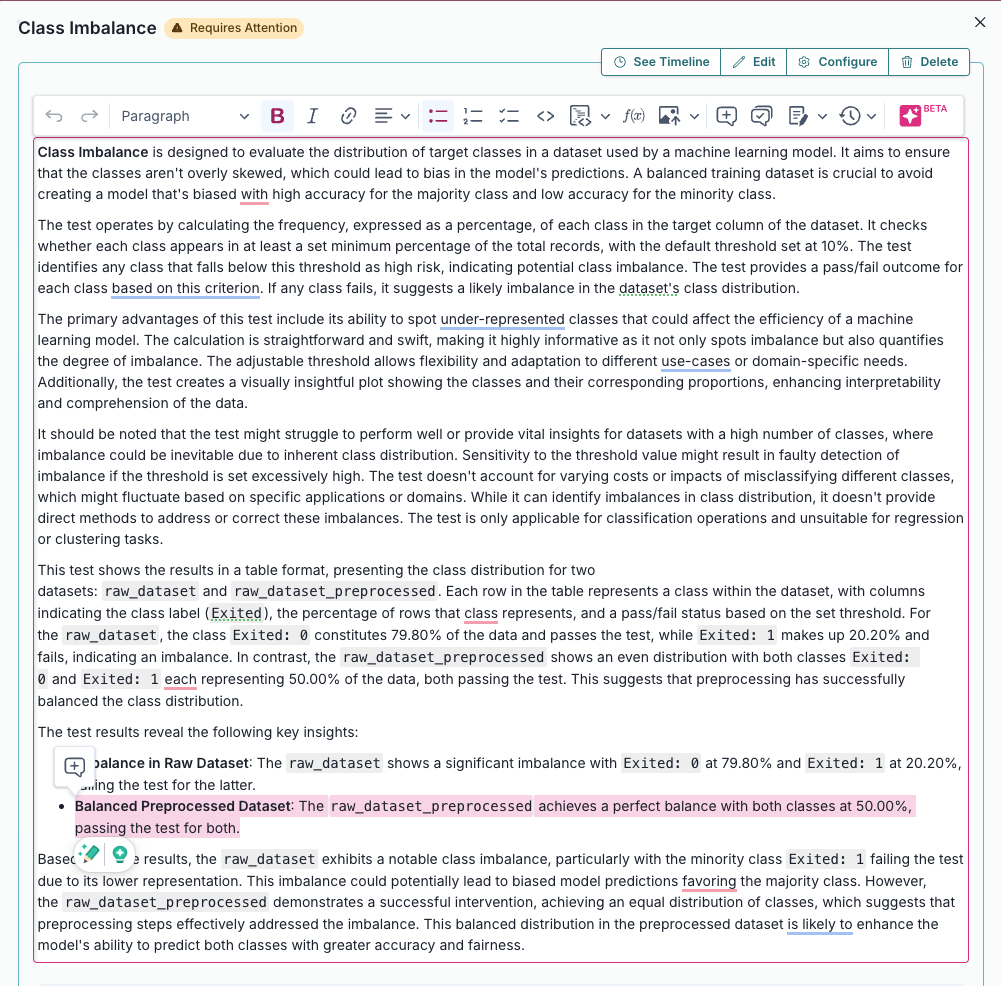
    • Click See evidence details to review the LLM-generated description that summarizes the test results, that confirm that our final preprocessed dataset actually passes our test:

    Screenshot showing the ClassImbalance test generated description in the text editor

Here in this text editor, you can make qualitative edits to the draft that ValidMind generated to finalize the test results.

Learn more: Work with content blocks

Preparing the preprocessed dataset

Split the preprocessed dataset

With our raw dataset rebalanced with highly correlated features removed, let's now spilt our dataset into train and test in preparation for model evaluation testing.

To start, let's grab the first few rows from the balanced_raw_no_age_df dataset we initialized earlier:

balanced_raw_no_age_df.head()
CreditScore Geography Gender Tenure Balance NumOfProducts HasCrCard IsActiveMember EstimatedSalary Exited
2910 542 France Male 8 101116.06 1 1 0 196395.05 0
6144 587 France Female 6 88820.29 1 0 0 70224.34 0
6561 724 France Female 3 132352.69 1 1 0 80320.30 0
2543 547 Germany Male 3 81290.02 3 0 1 177747.03 1
4793 659 France Female 9 23503.31 1 0 1 169862.01 1

Before training the model, we need to encode the categorical features in the dataset:

  • Use the OneHotEncoder class from the sklearn.preprocessing module to encode the categorical features.
  • The categorical features in the dataset are Geography and Gender.
balanced_raw_no_age_df = pd.get_dummies(
    balanced_raw_no_age_df, columns=["Geography", "Gender"], drop_first=True
)
balanced_raw_no_age_df.head()
CreditScore Tenure Balance NumOfProducts HasCrCard IsActiveMember EstimatedSalary Exited Geography_Germany Geography_Spain Gender_Male
2910 542 8 101116.06 1 1 0 196395.05 0 False False True
6144 587 6 88820.29 1 0 0 70224.34 0 False False False
6561 724 3 132352.69 1 1 0 80320.30 0 False False False
2543 547 3 81290.02 3 0 1 177747.03 1 True False True
4793 659 9 23503.31 1 0 1 169862.01 1 False False False

Splitting our dataset into training and testing is essential for proper validation testing, as this helps assess how well the model generalizes to unseen data:

  • We start by dividing our balanced_raw_no_age_df dataset into training and test subsets using train_test_split, with 80% of the data allocated to training (train_df) and 20% to testing (test_df).
  • From each subset, we separate the features (all columns except "Exited") into X_train and X_test, and the target column ("Exited") into y_train and y_test.
from sklearn.model_selection import train_test_split

train_df, test_df = train_test_split(balanced_raw_no_age_df, test_size=0.20)

X_train = train_df.drop("Exited", axis=1)
y_train = train_df["Exited"]
X_test = test_df.drop("Exited", axis=1)
y_test = test_df["Exited"]

Initialize the split datasets

Next, let's initialize the training and testing datasets so they are available for use:

vm_train_ds = vm.init_dataset(
    input_id="train_dataset_final",
    dataset=train_df,
    target_column="Exited",
)

vm_test_ds = vm.init_dataset(
    input_id="test_dataset_final",
    dataset=test_df,
    target_column="Exited",
)

In summary

In this second notebook, you learned how to:

Next steps

Develop potential challenger models

Now that you're familiar with the basics of using the ValidMind Library, let's use it to develop a challenger model: 3 — Developing a potential challenger


Copyright © 2023-2026 ValidMind Inc. All rights reserved.
Refer to LICENSE for details.
SPDX-License-Identifier: AGPL-3.0 AND ValidMind Commercial